 Ideas for a smarter digital life.
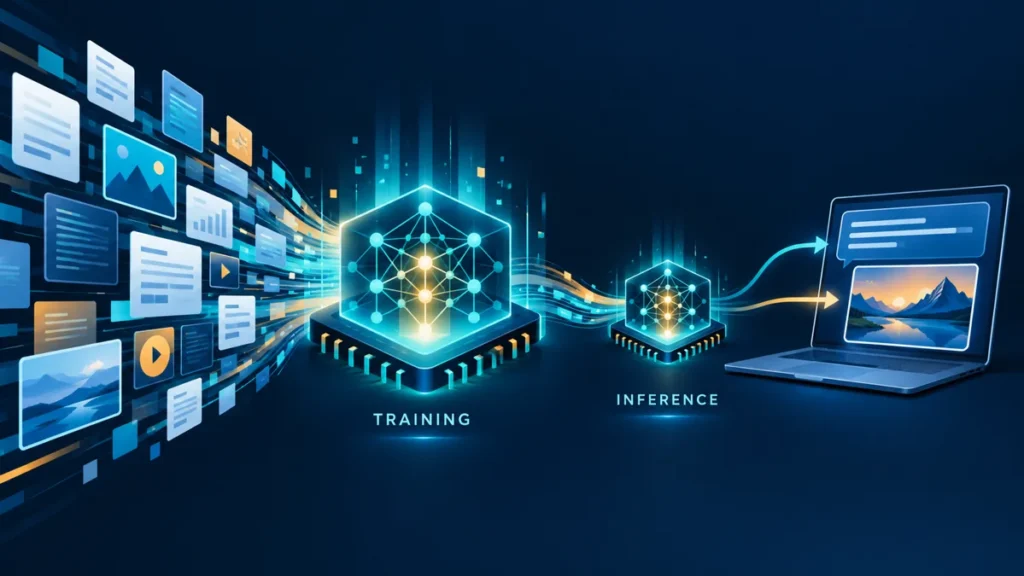
AI workloads are the computing tasks involved in preparing data, training or adapting models, and using those models to produce results. A chatbot response, an image-generation request and a model-training run are different workloads, even when they belong to the same application.
Understanding the difference helps you choose tools and ask better questions about performance and cost. This guide explains the main workload types, follows a simple document assistant through its stages, and shows what to measure before paying for more hardware.
What are AI workloads?
A workload describes the work a computer system must complete and the resources that work needs. With AI, this can include cleaning a dataset, adjusting learned model parameters, processing a prompt or checking prediction quality over time. Google Cloud groups these activities across the AI lifecycle, including data preparation, training, inference and monitoring. [1]
The workload is different from the model itself. A model is one component; the workload includes the operation being performed, its inputs and the computing environment. If you need a broader introduction, start with artificial intelligence explained.
Which types of AI workloads should you recognize?
| Workload | What happens | Simple example |
|---|---|---|
| Data preparation | Inputs are cleaned, organized or converted | Extracting usable text from scanned pages |
| Training | Learning adjusts model parameters | Learning patterns from labeled support tickets |
| Fine tuning | Additional training adapts an existing model | Adapting a classifier to company categories |
| Inference | A trained model processes new inputs | Predicting a ticket category or generating a reply |
| Evaluation and monitoring | Outputs and operation are checked | Measuring wrong answers and response times |
These stages can connect, but using an existing AI tool does not mean you personally run every stage. A hosted provider may handle the model infrastructure while your application sends requests. IBM identifies training and inference as two broad workload categories. [2]
How does AI training differ from inference?
Training changes what a model has learned by updating parameters. Inference applies a trained model to an input. Asking a chatbot to rewrite a paragraph is normally an inference request; it does not, by itself, establish that the model is being retrained on your message.
Their engineering priorities also differ. Large training jobs often emphasize processing many examples efficiently. Interactive inference must respond acceptably while serving changing numbers of users. AWS notes that inference can be sensitive to memory, latency and concurrent sessions, while training often prioritizes computational throughput. These are common patterns, rather than rules for every model. [3]
One inference request may be small, but repeated requests create ongoing demand. A model used by thousands of people needs a different deployment plan from the same model used occasionally by one person.
What does an AI workload look like in practice?
Consider an illustrative assistant that answers questions about a small team's approved help documents. This is a teaching example, not a performance test.
- The team extracts text from its documents and removes duplicate or obsolete pages.
- A retrieval system indexes useful passages so it can find relevant material.
- A user asks a question, and the application retrieves matching passages.
- A language model receives the question and relevant text, then generates an answer.
- A reviewer checks whether the answer matches the source and whether restricted information appeared.
The workflow contains preprocessing, retrieval, model inference and evaluation. It can use an existing trained model without training a new foundation model. Sending longer documents unnecessarily may add processing, so selecting relevant passages is a sensible design choice to test.
If files are stored online, our cloud storage guide explains that separate part of the setup. Storage keeps the files; the AI workload describes the processing performed with them.
Which resources affect AI workload performance?
Compute executes operations, memory holds active data and model state, and storage supplies files and saved model checkpoints. For a practical hardware comparison, see our CPU vs GPU guide, which explains when different processor types help with AI inference and training. Network capacity matters when data moves between services or machines. The limiting resource depends on the job. [1][2]
A small classifier may have modest requirements. A large language model with long inputs and many simultaneous users can demand much more memory and processing. Buying the fastest processor will not fix a slow document pipeline if most time is spent retrieving files.
Before choosing a deployment, write down the task, expected input size, typical request volume, acceptable response time and data restrictions. These requirements make hardware and service comparisons more meaningful than a generic claim that one system is best for AI.
How can you approach AI workload optimization?
Start by measuring one realistic task. For a document assistant, record the time to retrieve source passages, generate the answer and complete a quality check. Also record failures, cost per completed task and memory use where those measurements are available.
Then change one factor at a time. Try a smaller suitable model, shorter relevant inputs or a different batch size, and compare output quality as well as speed. For work without an immediate deadline, processing requests together may be worth testing. Interactive work needs attention to waiting time.
Keep a simple comparison log using the same sample questions. An improvement only counts if it preserves the accuracy and data-handling requirements of the task. AWS discusses caching and model compression as inference optimization options; neither provides a universal saving. [3]
Frequently asked questions
Does every AI workload need a GPU?
No. Requirements vary with model size, software and the task. CPU-based processing may be sufficient for smaller jobs. Check the model's documented requirements and test your actual use case before buying hardware.
Does an AI workload have to run in the cloud?
No. A workload can run locally, on a private server or through a hosted service. Choose based on capacity, operational effort, access controls and the information being processed.
Is using AI the same as training AI?
No. Generating a response usually uses a trained model for inference. Provider policies about retention or later training are a separate question and depend on the service and settings. See our guide to protecting client data when using AI tools.
What should a beginner measure first?
Measure whether the result is correct and useful, how long the complete task takes, and its cost. Those observations help identify whether the next improvement belongs in the model, the surrounding workflow or the infrastructure.
To understand models you can download and run yourself, read our guide to open weight models.
Sources
- Google Cloud — What is an AI workload
- IBM — What are AI workloads
- AWS — Challenges of inference compared to training
Sources reviewed 27 October 2026.